
Engineers who have already settled on a synthetic data generation method — whether a GAN, a statistical sampler, or an LLM-based synthesizer — quickly discover that producing data in production looks very different from running it in a notebook. A production pipeline must move records from a source to a consumer reliably, validate them along the way, and recover from drift without manual intervention. This article walks through the end-to-end architecture of such a pipeline: the three core stages, the three dominant execution patterns, and the Lambda versus Kappa trade-offs that determine how fresh the data feels to the consumer. It is written for engineers who need to operationalize generation, not to choose the underlying mathematical method.
A production synthetic data pipeline carries records from a source to a consumer through three stages — ingestion, transformation, and loading — regardless of whether generation is handled by a GAN, a statistical sampler, or an LLM synthesizer. The shape of each stage, however, looks quite different from a conventional ETL workflow.
For a synthetic pipeline the "source" is rarely a continuously changing upstream feed. It is typically a curated bundle of artifacts: a sample of real records that seeds the generator, a schema definition, and a constraint manifest that codifies business rules, referential integrity, and privacy budgets. Source signals may still flow from transactional databases, SaaS APIs, event streams, or seed files, but they are treated as configuration more than as data to be transported at high velocity (K2View). The canonical artifact at the end of ingestion is a versioned manifest that names the seeds, the schema, and the constraint set, so a downstream generator can be reproduced bit-for-bit.
This is where generation actually happens. A generator job runs the chosen model against the manifest and emits candidate records. Each candidate then passes through a stack of operations: schema validation, business-rule enforcement, deduplication, type casting, joins with reference tables, and quality filters that score fidelity, utility, and privacy risk (IBM, jobsbyculture.com). Common failure modes at this stage include hallucinated values, schema violations, mode collapse, and reward hacking — all of which is why filtering occurs at multiple points rather than as a single end-of-pipeline check (Confident AI, changegamer.ai). For synthetic data, transformation is both the most expensive and the most failure-prone stage: generation is non-deterministic, so two runs of the same job on the same inputs can produce materially different outputs.
The output is written to a destination — a warehouse, lake, feature store, or directly into a training pipeline — with lifecycle controls such as versioning, retention, and rollback (K2View, Fireworks AI). Write targets are deliberately typed so consumers know whether they are receiving raw generated records or quality-filtered, validated records.
The first architectural decision a team makes is the order of transformation versus loading (Kestra). ETL transforms and filters before write, which is the safer default when generation is expensive or when bad records must never reach the destination. ELT loads raw generated output and applies quality gates inside the warehouse, which trades downstream flexibility for a larger blast radius if drift or mode collapse goes undetected (Domo). In practice, synthetic pipelines usually adopt ETL for the generator output and finance the inner dimension modeling inside the warehouse — but the choice must be made explicitly, because it determines how failures surface and how recoverable the pipeline is.
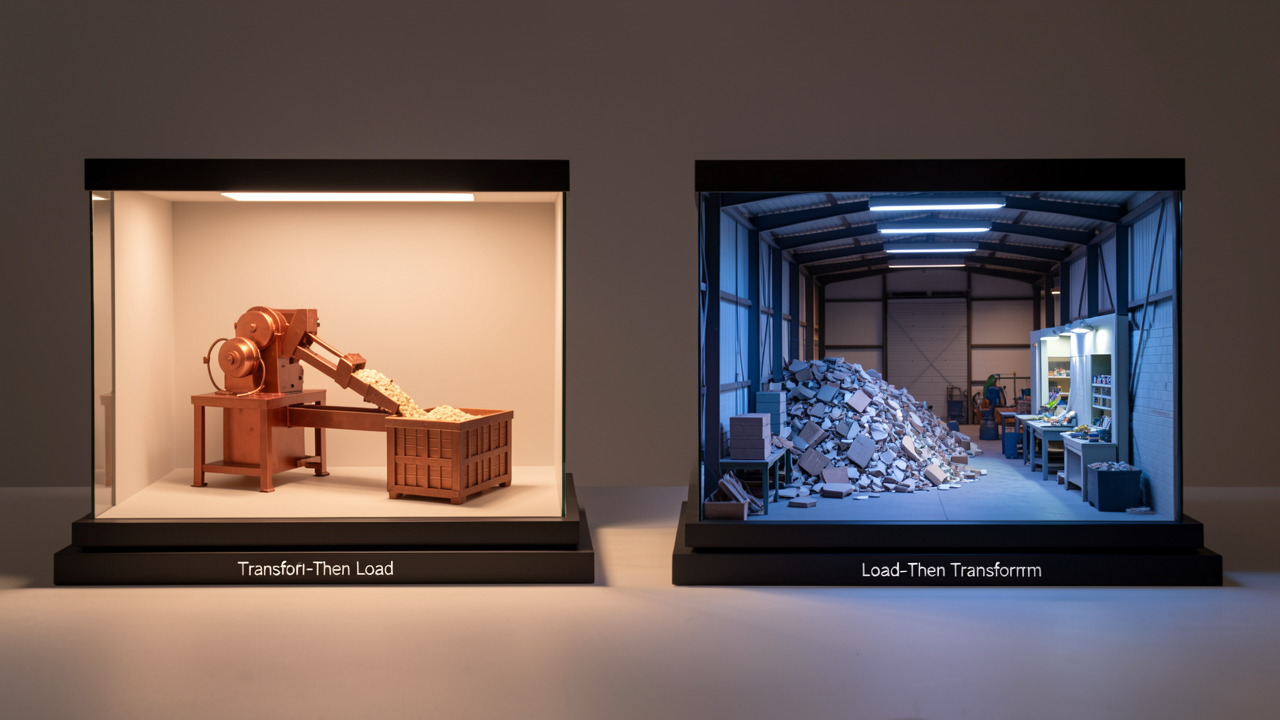
The traditional distinction between ETL (extract, transform, load) and ELT (extract, load, transform) is the order in which transformation and loading happen: ETL transforms data before it lands in the destination, while ELT loads raw data first and transforms it inside the warehouse (Kestra, Domo). For synthetic data, "transformation" is not just a SQL reshape — it includes stochastic generation itself, which is rarely cheap to re-run.
ETL fits a synthetic pipeline when generation is expensive, when constraints must be validated before records touch a shared destination, or when compliance review sits outside the warehouse. Typical signals include:
In these cases, validating outside the warehouse gives a clean failure boundary: bad generations never enter the system of record.
ELT makes sense when the warehouse is already the system of record and the team wants to amortize a single generation run across many consumers. This is the pattern documented for cloud-native warehouses like Snowflake and BigQuery, where raw rows land first and SQL shapes them into per-team views (Domo). Concrete conditions:
In conventional ETL, "transformation" is usually deterministic and idempotent; re-running it is cheap. For synthetic data, the generation step is stochastic and expensive — it consumes GPU time, licensed model calls, or both (Future AGI). That asymmetry tilts the default toward ETL: generate once, validate, then load curated batches. ELT remains attractive when the warehouse is already the trusted store and downstream teams genuinely need raw synthetic rows for their own modeling work.
A practical heuristic: pick ETL when privacy review, PII redaction, or heavy generation GPU work is involved; pick ELT when the warehouse is already the system of record and consumers want fast access to raw synthetic rows.
Batch pipelines run on a fixed schedule and process a bounded slice of records per run. They remain the default pattern for synthetic datasets that retrain models on a weekly or monthly cadence, because the operational surface area is small: a scheduler, an idempotent job, and a destination table or object store are usually enough. Freshness measured in hours is acceptable for offline evaluation sets, regression-test corpora, and periodic fine-tuning corpora. The cost profile is also predictable, since compute scales with the volume of each run rather than with continuous ingestion.
Micro-batch pipelines collect small windows of records — typically seconds to a few minutes — and process them as miniature batch jobs. This hybrid sits between the simplicity of batch and the timeliness of streaming. It is the sweet spot for ML teams that want fresh training signal without operating a full stream-processing stack: an e-commerce platform refreshing synthetic inventory features every two minutes is the canonical example. Micro-batch pipelines are appropriate when consumers can absorb a small delay in exchange for lower infrastructure complexity, predictable retries, and easier backfills than a true streaming topology offers (Domo). For most synthetic use cases, including CI regression gating and drift-priming sets, micro-batch delivers enough freshness without the ordering and state-management overhead of streaming.
Real-time streaming processes records continuously with sub-second to low-second latency. It is justified when downstream consumers are operational systems — fraud detection, personalization, alerting — that cannot tolerate minutes of staleness. The trade-off is real complexity: ordering guarantees, checkpointed state, exactly-once semantics, and partition rebalancing all become first-class operational concerns rather than edge cases. Each of those concerns is solvable, but the engineering and infrastructure cost is substantial compared with batch or micro-batch.
The safe default for a synthetic data pipeline is batch or micro-batch. Generation itself is rarely the bottleneck — synthesizer runtimes, evaluator scoring, and downstream validation usually dominate wall-clock time — and forcing generation into a streaming topology usually hurts cost more than it helps freshness. Reserve real-time streaming for pipelines with a concrete consumer contract that explicitly demands second-level freshness, and confirm that the synthesizer, validator, and delivery layer can all sustain that cadence. Most teams run a mix: batch for bulk offline corpora, micro-batch for near-real-time feature and evaluation refreshes, and streaming only where an operational system genuinely requires it (Kestra).
Lambda architecture keeps two parallel processing paths and merges them at read time. The batch layer re-derives accurate historical views by replaying the full source, while the speed layer emits low-latency views from the freshest events. A serving layer reconciles the two so that consumers see recent deltas from the speed layer sitting on top of a correct, replayable baseline from the batch layer (Domo, "AI Data Pipelines").
For a synthetic data pipeline, this is the right topology when:
The price is operational: two code paths, two storage systems, and a merge logic that has to handle out-of-order late-arriving records from both sides.
Kappa architecture discards the batch layer entirely and treats every record — generation, validation, delivery — as a stream event. When generation logic changes, the team rewinds the log and replays from the relevant offset to rebuild downstream state (Domo, "AI Data Pipelines").
This is the right topology when:
Kappa's weakness is that replaying a long log to fix a logic bug can be slow and expensive, and the architecture assumes the log itself is the durable system of record.
Use this short decision rule:
In practice, many production synthetic pipelines start Kappa-style and evolve toward Lambda once a stable batch re-derivation path becomes necessary for analytics or compliance.
Most synthetic pipelines get the generation and loading right and then quietly rot at delivery. Loading is the moment when a batch becomes addressable, which means it is also the moment when a downstream consumer can pin a bad row into a model checkpoint and keep it for weeks. Treat the post-generation stage as a deliberate gate: validate first, only then advertise the batch to the rest of the platform.
A version label is only useful if it can answer "which run made this?" weeks later. Production teams typically resolve the version to a record that bundles the generator checkpoint, generation parameters, random seed, generation date, and a content hash of the schema. Treat the schema itself as a versioned artifact; generator and schema should advance together, because a mismatched pair is the most common silent breakage. Pin the consumer-side reference (training job ID, eval harness run, feature-store slice ID) to the version it consumed — without that link, a regression in held-out accuracy has no diagnosis.
Most frameworks converge on a similar set of gates, and the labels are mostly interchangeable:
Failing the whole pipeline on a degraded batch blocks every downstream consumer and turns a recoverable incident into an outage. The common pattern is to route a failing batch to a quarantine zone with its full version metadata and check logs, alert on the quarantine event, and let unaffected batches continue. The quarantined batch becomes a debugging artifact, not a production incident.
After a batch clears the gates, fan it out to its real destinations: training jobs, evaluation harnesses, feature stores, BI dashboards, and external test environments. Each delivery should publish the version identifier the consumer pinned to, ideally into the same lineage store the rest of the data platform already uses (OpenLineage, Unity Catalog, DataHub). That record is what turns a synthetic pipeline from a generator into infrastructure that can be reasoned about.
NIST's guidance and most vendor implementations both treat validation as a release gate rather than a debugging afterthought, and version control of synthetic datasets is consistently called out as essential for reproducibility and for tracing downstream regressions.
Sources: NIST-aligned validation approach, synthetic data lifecycle and gates (cited via k2view.com), version control for production pipelines, three-dimensional validation framework.
Once a synthetic data pipeline is live, the generator and the world it models begin to drift apart. New user demographics, seasonal patterns, product changes, and shifting fraud tactics all push the real distribution in directions the synthesizer never saw during training. Without an active monitoring layer, the pipeline keeps delivering records that look plausible in isolation but quietly stop representing reality — a state often called synthetic staleness.
The core of any monitoring loop is a recurring comparison between two snapshots:
Divergence is measured per feature and per joint slice using statistical tests, clustering-based comparison, or learned distance metrics. Useful signals include univariate Kolmogorov–Smirnov or chi-square tests on each column, embeddings plus a distance score for high-cardinality or text fields, and a coverage check that flags novel regions of feature space appearing in real data but absent from the synthetic stream. Production logs and agent telemetry usually supply the raw signal: query characteristics, label distributions, and downstream evaluation scores that reveal when the synthetic set and the real set are no longer aligned.
Each metric is checked against a calibrated threshold. Crossing it should page an on-call engineer or, better, open a retraining ticket automatically. A common pattern in 2026 pipelines is to combine several metrics — for example, any of three monitored features breaching its threshold, or the joint embedding distance exceeding a rolling baseline by a configurable factor — so that single-feature noise does not trigger spurious retrains. Alerting should land in the same observability stack (Prometheus, OpenTelemetry, Datadog, or an AI-specific platform) used for the real-data side, so dashboards and runbooks are shared (jobsbyculture.com; dev.to).
The same divergence signal that fires an alert can schedule a generator retraining job. Two feedback patterns are common:
Either way, the validator from the earlier stage is reused as the gate: the retrained generator must match or beat the previous version on quality, constraint, and privacy checks before it is promoted (bluegen.ai; runpod.io).
Drift detection on the real-data side is now table stakes, but drift monitoring on the synthetic side is still uncommon in 2026. Teams that ship synthetic data without it tend to accumulate quality debt and eventually debug mysterious downstream training regressions with no audit trail. A working practice is to wire the same evaluators used on production traces into the synthetic pipeline, so the loop stays short and any divergence between synthetic evaluation results and real production behavior is investigated immediately rather than discovered months later (futureagi.com). The takeaway is straightforward: a synthetic pipeline is not done when it generates — it is done when it notices, corrects, and proves the correction.