
On a 128GB unified-memory machine, the choice between vLLM and Ollama is no longer about what fits in memory—it is about how each engine spends the bandwidth the machine actually has. The AMD Ryzen AI Max Plus 395 platform and128GB Apple Silicon Macs both expose roughly 96GB to the model and cache, but the two inference engines reach very different throughput ceilings on the same silicon. This article pairs published benchmark numbers with the architectural differences that explain them: PagedAttention versus the llama.cpp load-what-fits memory model, continuous batching versus serial queues, and the ~256GB/s memory-bandwidth wall that dominates local LLM inference. The target audience is a developer choosing an inference engine for a local workstation who needs to understand not just the numbers but why they diverge.
A "128GB unified-memory workstation" is not a single machine; it is a class of machines that share a defining property — a single pool of high-bandwidth RAM that both the CPU and the GPU draw from, with no PCIe handoff and no discrete VRAM partition. The two reference platforms for this article are the AMD Ryzen AI Max+ 395 (codenamed Strix Halo) and the 128GB Apple Silicon Mac lineup, most directly the M4 Max.
The Ryzen AI Max+ 395 is a monolithic APU built on TSMC 4N that places the CPU, GPU, and NPU on the same die behind a single memory controller (AMD Strix Halo explained — iTechGuides). The published specification is:
The key feature for LLM work is AMD Variable Graphics Memory (VGM), which lets the user convert up to 96GB of the pool — the same 75% slice that Apple uses — into addressable GPU memory, leaving roughly 32GB for the OS and CPU workloads. On consumer SKUs this is set in AMD Software: Adrenalin Edition under Performance → Tuning; on PRO SKUs it is a BIOS option (AMD blog — Variable Graphics Memory).
The 128GB M4 Max Mac exposes the same effective GPU ceiling: macOS reports a recommendedMaxWorkingSetSize of about 96GB on a 128GB machine, which is why Ollama and other Metal-backed runtimes show ~96GB rather than 128GB (Apple Silicon LLM memory limits — stencel.io). What the M4 Max changes is bandwidth — it is rated at roughly 546 GB/s across an 8-channel LPDDR5X-8533 interface, more than double Strix Halo's theoretical ceiling (cpu-monkey M4 Max vs Ryzen AI Max+ 395).
Both platforms fit a 70B-class quantized model comfortably; the difference is how fast tokens come out. LLM token generation is memory-bandwidth-bound: each new token requires streaming the full set of weights from memory once per step (pinggy — best hardware for self-hosting LLMs). Against that yardstick, Strix Halo's ~256 GB/s sits an order of magnitude below a discrete RTX 4090's ~1,008 GB/s. Apple Silicon gets closer, but still trails. Capacity decides whether the model loads; bandwidth decides whether it runs quickly — and on both 128GB unified-memory platforms, bandwidth is the constraint that any inference engine will hit first.
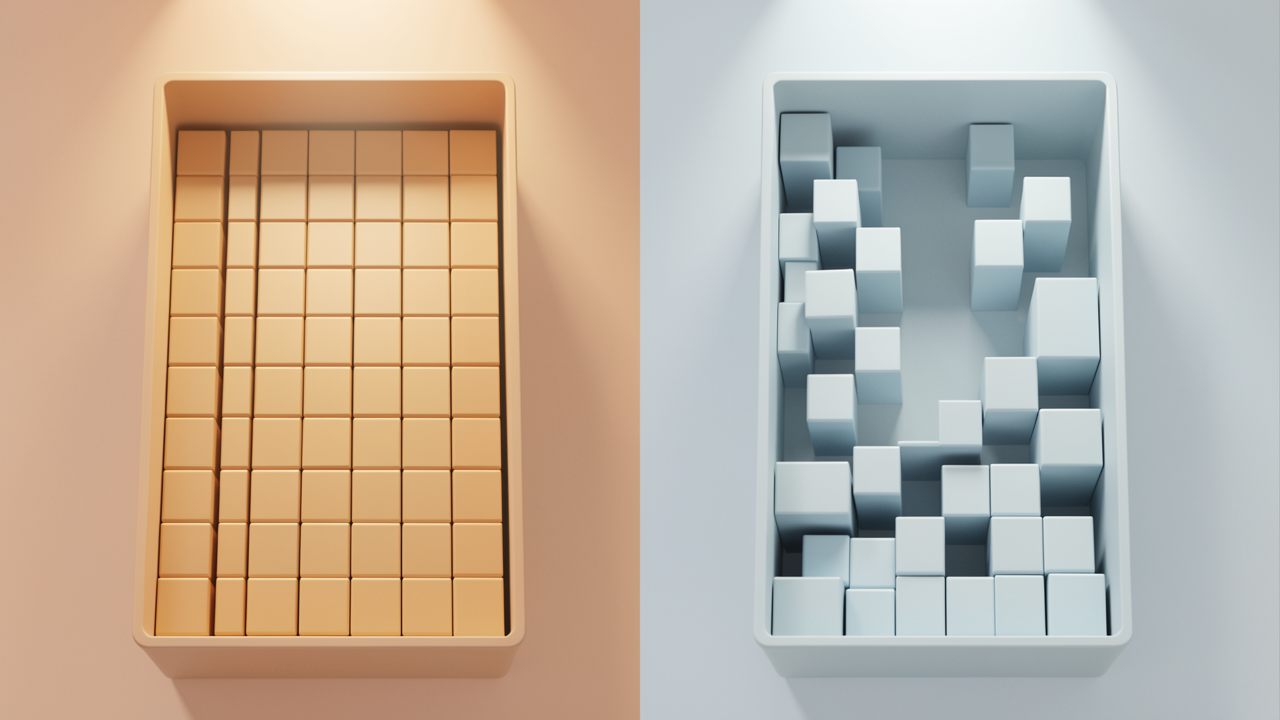
vLLM treats the KV cache the way an operating system treats RAM. Each request's key/value tensors are partitioned into fixed-size physical blocks (16 tokens of KV per block by default, configurable via --block-size), and a per-sequence block table maps the sequence's logical token positions to those physical blocks, which can live anywhere in memory and need not be contiguous (Kwon et al., SOSP 2023). The attention kernel is modified to gather KV vectors from these scattered blocks via the block table rather than reading one contiguous run.
Three sources of waste in naive contiguous allocation collapse under paging:
With PagedAttention, fragmentation is bounded to at most one partially-filled block per sequence. The original paper reports memory waste under 4%, compared to 60–80% wasted in prior serving systems (RunPod PagedAttention guide; Spheron LLM serving optimization). Blocks are allocated on demand as tokens stream out and freed immediately when a sequence finishes, which is what allows vLLM to sustain 2–4× more concurrent requests on the same memory budget (Frontier Checkpoint).
Ollama is a thin Go server that wraps llama.cpp. When a model is pulled, it is stored as a content-addressed GGUF blob on disk; at load time llama.cpp mmaps the tensors directly from that file, parses metadata, and applies any configured quantization (Towards AI overview of Ollama architecture). GGUF is purpose-built for memory-mapping quantized weights, which is why Ollama can start a multi-billion-parameter model in seconds on a laptop.
The KV cache, however, is handled differently. llama.cpp reserves it statically per request in contiguous slots sized for the request's max_tokens budget before generation begins; there is no per-block allocator analogous to PagedAttention (Spheron Ollama vs vLLM; bswen blog). The practical consequence is sharp: every concurrent request commits its full KV footprint up front, regardless of how many tokens it will actually emit.
The architectural divergence shows up directly in concurrency ceilings. On an H100 80GB serving Llama 3.1 8B, Ollama hits OOM around 40 concurrent requests, while vLLM sustains 180+ FP16 and 350+ FP8 requests on the same GPU, yielding roughly 2× the aggregate throughput at 32 concurrent users (Spheron benchmark). For a single user on a quiet machine, both engines look similar; under load, the static KV reservation is the binding constraint.
When only one user is asking the model to generate tokens, the architectural advantages of PagedAttention and continuous batching do not yet have anything to grip. Both engines spend almost all of their time on the decode loop, which means both are constrained by the same underlying physics: how fast the memory subsystem can move weights and KV-cache bytes.
llama3.1:8b Q4_K_M): ~420 tok/s, ~35 ms time-to-first-tokenLlama-3.1-8B-Instruct FP16): ~510 tok/s, ~28 ms time-to-first-tokenThe ~20% throughput gap is small enough that it largely disappears once you account for what is actually being measured. Ollama is running an aggressively quantized 4-bit GGUF checkpoint; vLLM is running FP16 weights. If you compared vLLM with the same Q4_K_M GGUF (or quantized AWQ on the vLLM side), the gap would shrink further. This is an important framing for the rest of the article: at single-user load, quantization policy — not engine architecture — is the dominant variable on a single GPU too.
Move the same workload to the AMD Ryzen AI Max Plus 395 platform (Strix Halo, 128 GB unified memory, LM Studio with the ROCm/llama.cpp runtime) and the numbers shift downward because the memory subsystem is fundamentally different — but they stay in a familiar band:
These are single-user, single-stream figures. They feel responsive for chat and RAG even at the low end, and AMD's own internal testing on a pre-production Ryzen AI Halo developer platform reports 36 output tok/s and 446 input tok/s sustained at a 128K context window using LM Studio with Vulkan llama.cpp — a useful cross-check on the order of magnitude.
The reason a single 8B model on a 256 GB/s memory subsystem sits in the 30–60 tok/s range regardless of engine is arithmetic, not software. At FP16, an 8B model's weights are ~16 GB; even at Q4_K_M they are ~5 GB. A decode step that touches every weight once plus a small KV-cache slice therefore has to move roughly one model-weight volume per generated token. On a 256 GB/s link (measured around215 GB/s in practice on Strix Halo), a5–16 GB memory transaction lands in the 30–60 tok/s window that the MindStudio and Spheron numbers both reflect.
That is the ceiling the rest of this article argues against — and the ceiling that vLLM's batching design later cracks wide open.
On an H100 SXM5 80GB, the divergence between the two engines becomes unmistakable as soon as more than one request lands in the queue. Spheron's Ollama vs vLLM benchmarks (Llama 3.1 8B, 100-token prompt / 200-token generation) show Ollama holding at roughly 310–320 tok/s total whether there are 8 or 32 concurrent requests in flight—its single-instance queue serializes them, so adding more load produces no aggregate gain. vLLM on the same card climbs to about 1,100 tok/s at 8 concurrent and roughly 1,450 tok/s at 32, because continuous batching absorbs new requests into the next forward pass instead of parking them behind a finished sequence (Spheron, March 2026). Time-to-first-token under 32 concurrent load tells the same story: ~290 ms for Ollama versus ~95 ms for vLLM.
The pattern repeats on consumer and workstation GPUs. On an RTX 4090 with 50 concurrent users serving Llama 3.1 8B, GingerLabs records vLLM at 920 tok/s with a 2.8-second p99 latency, while Ollama manages only 155 tok/s with a 24.7-second p99—close to typical request timeouts. SitePoint's 2026 benchmark confirms the same numbers from a different harness and adds that vLLM's p50/p95 latencies stay flat (1.8 s / 2.1 s at 50 users) while Ollama's blow out to 12.1 s and 18.4 s. On a Blackwell-class RTX Pro 4500, the gap widens further: vLLM NVFP4 reaches 4,870 tok/s with ~13 ms TTFT, while Ollama's single-instance stream is stuck at 134 tok/s and—critically—does not scale with additional concurrent users on the same process.
The tail-latency picture is equally stark. On identical hardware, Red Hat–cited figures published by GingerLabs show vLLM at 793 tok/s with an 80 ms p99 TTFT versus Ollama at 41 tok/s with a 673 ms p99 TTFT—an 8× TTFT gap and roughly a 19× throughput gap. That p99 divergence is the operational difference between a usable service and a queue that visibly stalls under load.
On a 128GB unified-memory workstation the same architectural asymmetry applies: PagedAttention and continuous batching still give vLLM a scheduler-level advantage that Ollama's FIFO model cannot match. What changes is the absolute ceiling. Both engines are now memory-bandwidth-bound on the roughly 256 GB/s LPDDR5X bus exposed by AMD Ryzen AI Max Plus 395 and 128GB Apple Silicon SoCs, so the H100-scale numbers above are upper bounds rather than predictions. The scheduler decides how much of that bandwidth is wasted on queueing and padding; the memory bus decides how many tokens per second can ever leave the package.
Every benchmark gap between vLLM and Ollama on a 128GB unified-memory workstation traces back to a single physical ceiling: the memory bus.
LLM decode is fundamentally a memory-bandwidth-bound workload. Generating one token requires streaming the entire parameter footprint through memory every step—the arithmetic is cheap, the data movement is not. On Strix Halo, the 256-bit LPDDR5X-8000 bus delivers roughly 256 GB/s theoretical and around 212–215 GB/s in practice, and a 40GB quantized 70B model on that pipe yields about 5 tokens per second at FP16/Q8 and up to 12–15 tok/s at aggressive Q4 (a Q4 model is lighter on bandwidth because fewer bytes must be streamed). The 128GB capacity is what lets the model load at all; the 256-bit bus is what determines how fast it talks. Crucially, the RAM is soldered LPDDR5X because a socketed DDR5 channel physically cannot reach this bus width.
The same relationship holds on Apple Silicon. The M4 Max offers 128GB of unified memory at 546 GB/s—an RTX 4090 still wins on bandwidth at 1,008 GB/s, but cannot match the capacity. Unified memory eliminates the PCIe transfer tax, so what you measure in tokens per second is essentially the memory bandwidth divided by the working-set size.
This is where the engine architecture collides with the physics. PagedAttention cannot raise the bandwidth ceiling—it can only reduce wasted bandwidth on unused KV cache slots. By allocating 16-token blocks on demand and bounding fragmentation to at most one partially-filled block per sequence, PagedAttention cuts KV-cache waste from 60–80% down to under 4%, which translates directly to 2–4× more concurrent sequences for the same bandwidth budget.
On a discrete GPU with hundreds of GB/s of headroom, that amortization compounds into dramatic throughput wins. On Strix Halo, the absolute gain shrinks because total bandwidth is fixed: amortizing wasted KV bandwidth still helps, but you cannot create bandwidth that does not exist. Ollama's lower single-stream tok/s on the Ryzen box reflects this ceiling rather than llama.cpp inefficiency—the same model on the same bus with the same bandwidth budget will top out near the same tok/s regardless of how KV cache is laid out.
The proportional advantage persists, however. vLLM still amortizes KV bandwidth across batched sequences through continuous batching, while Ollama processes requests serially. The two engines reach different points on the same curve: vLLM trades per-sequence latency for aggregate throughput, Ollama preserves single-stream responsiveness. Neither escapes the ~256 GB/s wall.
The architectural comparison between vLLM and Ollama is real, but on the two target platforms the user's freedom of choice is narrower than the benchmark charts suggest. On both Apple Silicon and AMD Strix Halo, vLLM's native code path is CUDA, and neither machine is an NVIDIA box.
On Apple Silicon, the stock macOS vLLM build does not use the GPU at all. The vLLM core kernels — PagedAttention, the fused residual-norm-attention sequence, and the custom attention variants — are written against the CUDA programming model, which depends on virtual-memory primitives that Metal Performance Shaders does not expose in the same form. The macOS port therefore falls back to a CPU backend, and the numbers are punishing: roughly 3–5 tokens per second aggregate on an M5 Max running Llama 3.1 8B at batch size 4, versus about 92 tokens per second for llama.cpp's native Metal backend on the same hardware and model — a gap on the order of 20–30× (vLLM-MLX integration analysis).
vLLM-Metal exists as a community plugin that replaces the CUDA backend with MLX and does reach the GPU. The startup log confirms it:
INFO: MLX device set to: Device(gpu, 0)
INFO: PyTorch device set to: mps
INFO: Metal memory: 51.5GB total, 18.9GB available
INFO: KV cache: 35010.4 MB (24 layers, 178072 blocks)
INFO: Native paged-attention Metal kernels loaded
So the path is genuinely GPU-accelerated, not a CPU fallback (vLLM-Metal Hello World). The problem is that the CUDA-to-Metal translation bridge does not implement PagedAttention efficiently because of the underlying memory-model mismatch, and throughput on the same workload ends up meaningfully worse than llama.cpp's hand-tuned Metal kernels — close enough that Ollama (llama.cpp + Metal) remains the default recommendation for Apple Silicon local inference (KunalGanglani).
On the AMD Ryzen AI Max Plus 395 (Strix Halo), the constraint is different but equally one-sided. Strix Halo's iGPU is RDNA 3.5, and while vLLM lists AMD GPUs among its supported hardware, it does not have a stable ROCm production path on this platform today. The practical inference stack is llama.cpp, surfaced through Ollama or LM Studio. A developer evaluating the two engines on this hardware is effectively choosing between Ollama and an experimental vLLM-Metal build that, even where it works, does not yet match llama.cpp's native backend. The architectural story still matters — PagedAttention versus load-what-fits and continuous batching versus serial queues still explain the divergence — but on Ryzen AI Max Plus 395 the user mostly gets to run only one of the two engines.
On a 128GB unified-memory workstation, the choice between vLLM and Ollama collapses into a single question: which engine has a working, performant backend on the silicon in front of you. Today, that answer is Ollama on every supported platform, and vLLM on none of them.
The path that actually works is ROCm llama.cpp reached through Ollama or LM Studio. Community testing on a Ryzen AI Max Plus 395 board with Mesa RADV Vulkan measured roughly 215 GB/s of effective bandwidth against a theoretical 256 GB/s peak (runaihome.com), and that ceiling translates directly into the throughputs you can expect:
These numbers match the bandwidth-bound regime and are consistent with measurements from a separate ROCm llama.cpp run via LM Studio that reported "just under 40 tok/s" for a 9B-with-drafter setup and "around 30 tok/s" for GPT-OSS 120B at full precision (mindstudio.ai). vLLM has no documented drop-in ROCm path that targets Strix Halo; the project's ROCm support is aimed at MI-series data-center accelerators, and the consumer APU is not on the supported list.
Ollama with the llama.cpp Metal backend is the only practical GPU-accelerated option. On M-series hardware, Ollama delivers 40–60 tok/s on 8B models via Metal (kunalganglani.com). vLLM-Metal exists as an experimental community plugin and is consistently slower than llama.cpp Metal in controlled comparisons — Docker's own benchmark of Llama 3.2 1B showed llama.cpp at ~339 tok/s versus vLLM-Metal at ~275 tok/s across output lengths, a roughly 1.2–1.3× gap (docker.com), and on an M5 Max at batch size 8 the vLLM compatibility layer managed only ~12 tok/s against llama.cpp's 92 tok/s (contracollective.com).
For a developer whose primary workload is one user typing prompts into a local model, Ollama wins on fit-for-purpose: a mature backend, broad model catalog, and bandwidth-bound throughputs on every unified-memory platform tested. For multi-user or batched API serving — workloads where vLLM's continuous batching and PagedAttention would in principle shine — the architectural advantage is real but unreachable on Strix Halo or Apple Silicon today, because neither a production ROCm APU path nor a competitive Metal path exists.
Pick Ollama for the128GB unified-memory workstation you have today, regardless of whether it is a Ryzen AI Max Plus 395 mini-PC or a 128GB Mac. Revisit vLLM when its ROCm and Metal paths stabilize and demonstrate competitive throughput on the same silicon.