
Data engineers building agent-ready infrastructure face a recurring fork in the road: copy data into a warehouse before AI can touch it, or let AI query the data where it lives. MindsDB's federated query engine represents the second path, executing SQL against live sources rather than materializing them. Traditional ETL pipelines, by contrast, assume that agents, RAG systems, and embedding stores need a curated, centralized substrate. This article compares the two architectures on the dimensions that matter for AI workloads: data freshness, query latency, operational burden, and failure modes. The goal is to give data engineers a defensible framework for choosing between federated access and full ETL when wiring agents to enterprise data.
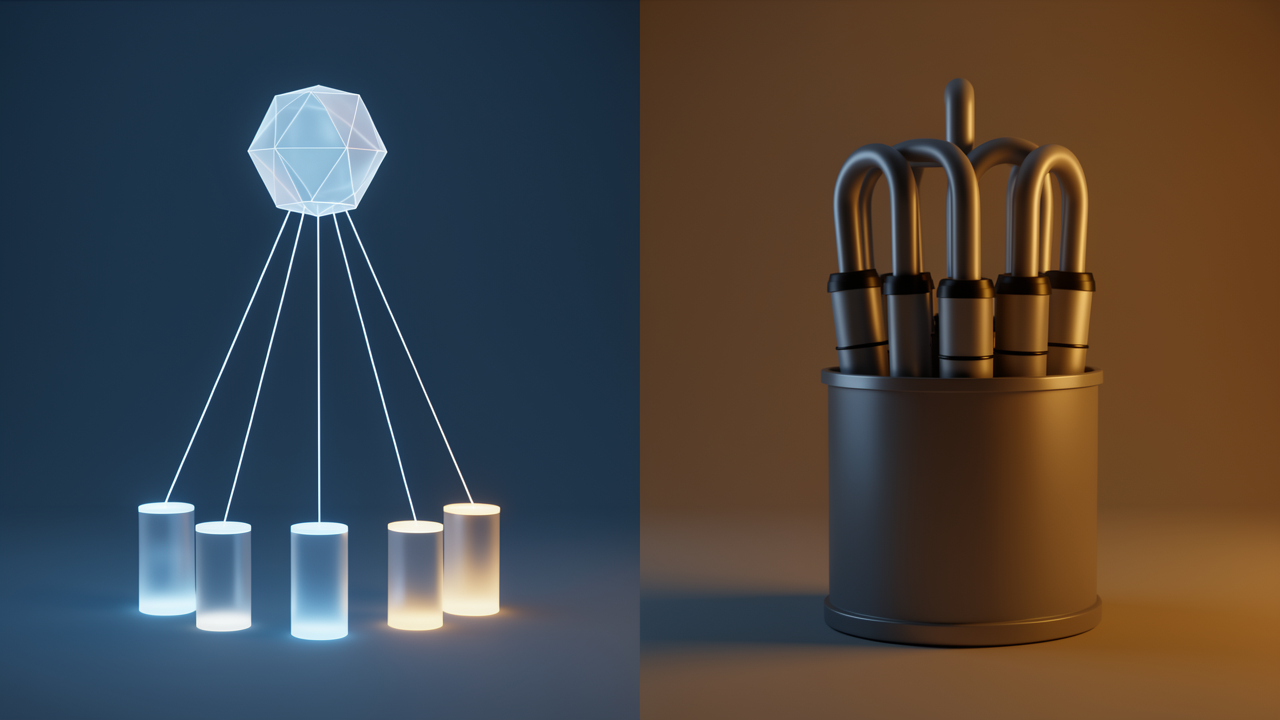
The two models diverge on a single structural question: where does the data live when an agent needs it?
MindsDB's federated query engine executes SQL at the source rather than moving rows. An agent issues a query; MindsDB routes the work to native handlers that speak each system's protocol, and joins happen across Postgres, MongoDB, REST APIs, and SaaS endpoints without materialization. The query engine exposes a single MySQL- or PostgreSQL-compatible endpoint, so the agent never holds multiple connections.
The documented workflow is Connect → Unify → Respond (MindsDB on PyPI):
Because data stays in place, there is no duplication, no sync delay, and no per-source integration code. The tradeoff is that the slowest source in a cross-system join sets the latency ceiling.
The ETL model answers the same question in reverse. Extract from sources, transform into a warehouse- or lake-friendly shape, load into curated tables, and only then point embedding jobs and vector stores at the result. The architecture assumes agents need a polished, governed substrate before they can act. Movement is the price; control, consistency, and predictable performance are the return.
Federated access trades movement for live joins. Centralized copies trade movement for control. The rest of this comparison — freshness, latency, operational burden, and failure modes — flows from that single architectural choice.
When an agent issues a query, MindsDB pushes the SQL down to the source system, so the result reflects whatever is currently committed in that database, not what was true at the last sync window. A row written to Postgres one second ago is visible to the agent one second later; there is no extractor to schedule, no landing table to load, and no embedding index to refresh. For structured sources, this collapses an entire class of staleness bugs that plague ETL-fed architectures.
ETL-fed RAG systems do not enjoy that property. A document store and a vector store are two independent systems that must be kept in step, and in practice they drift. The failure mode is well documented: documents change upstream, the vector index does not, and the agent retrieves vectors that no longer correspond to the underlying text. Retrieval returns results without errors, the LLM composes a confident answer, and the answer is quietly wrong. Industry write-ups on production RAG flag ignoring document updates and embedding drift among the most common causes of silent quality regression, and treat them as ongoing operational concerns rather than one-time fixes.
The financial shape of "ongoing" is concrete. At typical OpenAI embedding pricing of roughly $0.13 per million tokens, a million documents averaging 1,000 tokens costs about $130 to embed. Stretch that to 10 million documents refreshed once per month, and the bill lands near $13,000 per month in embedding spend alone, before any storage, compute, or LLM cost. That figure also assumes the embedding model is stable. Swap in a newer model, for cost or quality reasons, and the entire index is invalidated: vectors produced by model A are not commensurate with queries embedded by model B, so retrieval becomes unreliable. The remediation is a full re-index, a blue-green migration, shadow traffic, and rollback paths, all of which must be engineered and rehearsed.
MindsDB sidesteps the structured-data half of this entirely, because the source row is the source of truth, and it short-circuits the document half by writing vectors only when the agent actually needs them, rather than maintaining a continuously stale global index.
A retrieval-augmented generation request has to fit inside an end-to-end budget that documented production systems land between roughly 500 milliseconds and 5 seconds, depending on the use case (Kestra). That envelope has to cover embedding the query, retrieving candidates from a vector store, re-ranking the top-k with a heavier cross-encoder, and streaming generation back. Multi-query expansion plus stacked rerankers are known to push P99 off a cliff, so anything that adds even a few hundred milliseconds upstream is felt by the user (dev.to). Data freshness has to be squeezed into that same window.
MindsDB treats the source database as the executor. When a SQL statement arrives, the engine translates its predicates, projections, and join conditions into the native dialect of each underlying system — Postgres, MongoDB, REST APIs, and others reachable through the same query engine (GitHub). The source uses its own indexes and execution plan; MindsDB only receives the projected rows that survive the join (Daily Dose of DS). Because nothing is copied, there is no ETL window to wait through, no re-embedding batch to schedule, and no vector index to rebuild before the agent can answer. The agent reads current state on every request.
In an ETL-fed RAG stack, the answer path is a chain: the warehouse refresh runs on a schedule, the embedding job ingests the new rows, and the vector store is updated, only after which a vector lookup can return. Any of those stages can leave the index hours behind the source of record. Even a vector store that returns nearest neighbors very fast cannot compensate if the documents being searched were already stale when they were indexed.
Federated latency is bounded by the slowest source in the chain. A slow SaaS API, a cross-region Postgres read, or a paginated REST endpoint will dominate end-to-end time regardless of how clean the SQL translation is. The engine wins on freshness; the slowest connector sets the floor.
A traditional pipeline that prepares unstructured data for an agent or RAG system is rarely one job. It is a chain of moving parts, each with its own deployment, monitoring surface, and failure mode:
Five stages, five things to alert on, five places where a partial failure (stale chunk, dropped batch, schema drift in the source) can silently degrade retrieval quality without breaking the pipeline.
MindsDB collapses most of this into declarative SQL. A typical setup is a CREATE KNOWLEDGE_BASE statement, an INSERT INTO to ingest, and optionally a JOB plus TRIGGER to keep the index fresh — all reachable from any MySQL or PostgreSQL client. Knowledge Bases bundle chunking, embedding model selection, and vector storage into a single object, so the "five-stage stack" is replaced by one query layer.
Recent releases have tightened that surface further. In v26.0.0, the default Knowledge Base store in Docker Compose was switched to pgvector, and Knowledge Base inserts are now batched by default — removing two common tuning steps. v26.1.0 followed with fixes around provider configuration, notably that Knowledge Base creation now succeeds without explicit provider configurations for non-OpenAI scenarios, and the Azure provider was corrected.
Two caveats keep the comparison honest. Knowledge Bases do ingest embeddings, so MindsDB is not pure federation for unstructured data — there is still a vector store and an embedding call in the loop. And MindsDB retains JOBS and TRIGGERS precisely for the cases where pushdown is not enough, such as pre-aggregating or materializing derived views. The point is not the absence of infrastructure, but a smaller, more uniform surface area: one engine, one SQL dialect, and one set of release notes to track instead of five.
A federated engine removes the warehouse but inherits the weaknesses of every source it touches. The following failure modes are not edge cases; they are structural consequences of executing SQL where the data lives.
Latency is bounded by the slowest leg. MindsDB's own documentation acknowledges that "the performance of real-time AI workflows can be limited by the slowest connected data source in the chain" (Free AI Toolbox). A REST API with rate limits or a SaaS endpoint with multi-second response time will dominate any JOIN that includes it, regardless of how fast the database side is.
Cross-source JOINs require a pull side. MindsDB pushes predicates down to native databases "whenever possible, optimizing queries for efficient execution at the data source" (BusyBrain). That optimization only works when one side of the JOIN can execute the join locally. For a heterogeneous JOIN — Postgres to MongoDB, for example — at least one side must be materialized in MindsDB's execution buffer, so the smaller relation has to be the pushable one. Reverse that, and the engine drags rows across the network.
Transactional consistency is weak. Each source is read independently in the federation, so source A and source B are not seen at the same point-in-time. The seconds-long gap between reads can produce write skew that a warehouse snapshot would have hidden. Agents that reason over a "current" view of the world inherit this skew.
Source-side load is now agent-driven. The same query that a human analyst ran once a day can be issued by a popular agent hundreds of times per minute. Operational databases that were sized for OLTP traffic, not read-heavy AI workloads, become the bottleneck, and the failure is usually visible only when production starts to slow.
Governance lives in two places. MindsDB enforces its own role-based access on top of the source's native ACLs (BusyBrain). The two policies must be kept in sync manually; drift means either over-permissive access or broken queries. Traditional ETL centralizes this concern, at the cost of the freshness tax.
These are the trade-offs a data engineer must price in before wiring an agent directly to operational systems.
A defensible choice between federated access and full ETL comes down to where it lives, how fresh it must be, who maintains the plumbing, and what kind of analytics run on the query.
Default to federated access (MindsDB-first) when:
Default to ETL-first when:
Default to hybrid when:
Version-sensitive caveat: On MindsDB v26.0, the default Knowledge Base store in Docker Compose switched to pgvector, inserts are batched by default, and Dspy / ChromaDB / all ML handlers are deprecated. Faiss knowledge bases on v25.14+ use a flat index. Plan upgrades accordingly — a "stable vector store" today can change shape on the next minor.